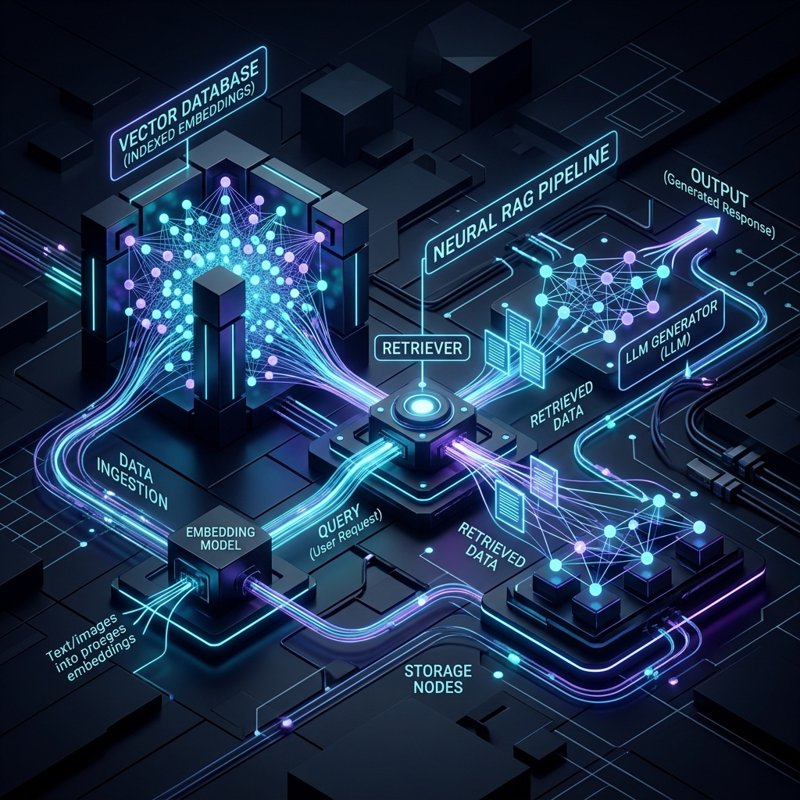
Production RAG Architecture
Taking Retrieval-Augmented Generation (RAG) applications from local demo notebooks into high-throughput production requires solving latency bottlenecks, hallucination risks, and LLM API rate limits.
3 Key Architectural Pillars
- ▸Semantic Chunking & Embedding: Replacing fixed character splitters with document-structure aware chunking (512 tokens with 50-token overlap).
- ▸Hybrid Vector & BM25 Search: Combining Pinecone dense vector embeddings with sparse BM25 keyword matching for high-precision retrieval.
- ▸Cross-Encoder Re-Ranking: Reranking top-20 retrieved candidates down to the 5 most relevant context passages before prompt injection.
Fallback LLM Model Orchestration
By integrating FastAPI orchestrators with Model Context Protocol (MCP) tool execution and automated fallback routing (OpenAI → Anthropic → Local VLLM), service uptime is guaranteed even during primary LLM provider outages.